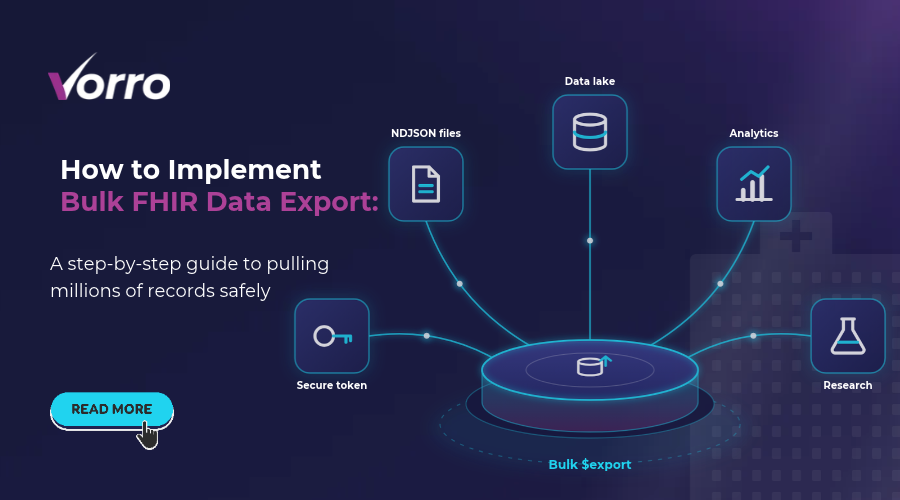
How to Implement Bulk FHIR Data Export: A Step-by-Step Guide
If you’ve ever stared at a FHIR server and wondered how to pull millions of records without choking the network, you’re in the right spot. In this guide I’ll walk you through how to implement bulk FHIR data export from start to finish, with code snippets, real-world tips, and the performance tricks most docs skip.
Introduction to Bulk FHIR Data Export
Bulk export isn’t just a nice-to-have; it’s the backbone of population health dashboards, research data lakes, and any analytics platform that needs a snapshot of a whole ecosystem. Pulling data one patient at a time would take forever – the $export operation lets you ask the server for everything in one asynchronous job.
Why bulk export matters for interoperability
Think about a statewide quality-improvement program. They need every asthma encounter from every clinic, updated nightly. Bulk export delivers that data in a single, standards-based package, making downstream ETL pipelines far simpler. Without it, each vendor would have to craft a custom extractor – a maintenance nightmare.
Key specs – HL7 Bulk Data Access IG v4.0
The official guide is the HL7 Bulk Data Access Implementation Guide version 4.0. It defines the $export operation, the asynchronous flow, and the approved output formats (NDJSON, CSV, JSON). The spec also spells out required server capabilities – you’ll see those in the conformance statement.
Prerequisites and Environment Setup
Required FHIR server capabilities
Before you write a single line of code, verify that your server advertises the BulkDataExport capability in its CapabilityStatement. Look for a section like:
{
  "resourceType": "CapabilityStatement",
  "rest": [{
    "resource": [{
      "type": "Patient",
      "operation": [{
        "name": "$export",
        "definition": "http://hl7.org/fhir/OperationDefinition/Patient-export"
      }]
    }]
  }]
}
If you don’t see it, you’ll need to enable the module or switch to a compliant host.
Authentication OAuth2 SMART on FHIR
Bulk export uses the client-credentials flow. Your client gets a token with the system/*.read scope (or a narrower patient/*.read if you’re limiting to a cohort). Here’s a quick curl example:
curl -X POST https://auth.example.com/token \
  -d 'grant_type=client_credentials' \
  -d 'client_id=bulk-export-app' \
  -d 'client_secret=YOUR_SECRET' \
  -d 'scope=system/*.read'
The response gives you an access_token you’ll attach to every $export request.
Tools and libraries
Most devs reach for curl or Postman for quick tests. For production code, the HAPI-FHIR Java SDK and the SMART-on-FHIR Python client handle token refresh and header management out of the box; meanwhile, a recent review of top Mirth alternatives in 2026 can help you choose the right integration engine. I’ll sprinkle a little Node.js pseudo-code later to keep things language-agnostic.
The $export Operation – Core Workflow
Building the initial request
A $export call is just an HTTP GET to /Group/{id}/$export, /Patient/$export, or /$export for a system-wide export. You can add query parameters like _type=Observation,Condition to limit resources, or _since=2023-01-01 for incremental pulls.
Asynchronous processing and status polling
The server immediately replies with a 202 Accepted and a Content?Location header that points at the status endpoint. That URL stays alive for up to 24 hours, giving you time to poll for completion.
Handling response formats NDJSON CSV JSON
The spec mandates NDJSON as the default because it streams nicely. Some servers also let you ask for CSV (_outputFormat=application/ndjson vs application/csv). Pick NDJSON for massive dumps – you can pipe it straight into Spark or Athena.
Step-by-Step Implementation Guide
1?? Initiate the export request
Here’s a concise Node snippet using axios:
const axios = require('axios');

async function startExport(token) {
  const response = await axios.get('https://fhir.example.com/$export', {
    headers: { Authorization: `Bearer ${token}` },
    params: { _type: 'Patient,Observation', _outputFormat: 'application/ndjson' }
  });
  if (response.status !== 202) throw new Error('Export not accepted');
  return response.headers['content-location'];
}
That content-location value is your ticket to the next stage.
2?? Store the Content-Location header
Persist the URL in a database or a durable queue. If your service crashes, you can resume polling without restarting the export.
3?? Poll for completion status codes exponential back-off
A naive loop that hits the endpoint every second will get you rate-limited fast. Instead, use exponential back-off with jitter:
async function pollStatus(url, token) {
  let delay = 2000; // start with 2?seconds
  while (true) {
    const res = await axios.get(url, { headers: { Authorization: `Bearer ${token}` } });
    if (res.status === 200) return res.data.output; // job done
    if (res.status === 202) {
      await new Promise(r => setTimeout(r, delay));
      delay = Math.min(delay * 2, 30000); // cap at 30?seconds
    } else {
      throw new Error(`Unexpected status ${res.status}`);
    }
  }
}
The output array contains URLs for each file generated.
4?? Retrieve result files
Each file URL can be fetched with a simple GET. For large files, stream the response to disk or directly into a processing engine:
const fs = require('fs');
async function downloadFile(fileUrl, token, dest) {
  const response = await axios.get(fileUrl, {
    responseType: 'stream',
    headers: { Authorization: `Bearer ${token}` }
  });
  response.data.pipe(fs.createWriteStream(dest));
  return new Promise((resolve, reject) => {
    response.data.on('end', resolve);
    response.data.on('error', reject);
  });
}
Remember to honor any Retry?After header if the server throttles you.
5?? Validate and parse NDJSON streams
NDJSON is line-delimited JSON – each line is a valid resource. Use a streaming parser (Node’s readline, Python’s ijson) so you never load the whole file into memory. Here’s a quick Node example:
const readline = require('readline');
async function processNDJSON(filePath) {
  const fileStream = fs.createReadStream(filePath);
  const rl = readline.createInterface({ input: fileStream });
  for await (const line of rl) {
    const resource = JSON.parse(line);
    // Insert into your data lake, or run validations
  }
}
Validate each resource against the FHIR schema – the HAPI validator or the official FHIR validator JAR are solid choices.
Security and Compliance Considerations
Token refresh and scopes
Access tokens expire after an hour by default. Build a refresh routine that re-authenticates with the client-credentials flow before the export completes. Keep the scope as narrow as possible – a system-wide system/*.read is overkill if you only need a specific group.
Data encryption at rest and in transit
All HTTP traffic must be TLS?1.2+; any file you store should be encrypted using AES?256 or a cloud-native KMS. If you’re dumping to S3, enable server-side encryption and apply bucket policies that restrict IAM roles.
Auditing export activities
Compliance frameworks like HIPAA demand an audit trail. Log every export request with timestamp, client ID, resource types, and the final file locations. CloudWatch or Elastic-Stack make searching those logs painless.
Performance and Scaling Strategies
Parallel file downloads
Most servers split the output into 5?10 MB chunks. You can fetch them concurrently – just respect the server’s Retry?After and Rate?Limit?Remaining headers. A thread pool of 12?16 parallel workers usually balances bandwidth and CPU usage on a modern VM.
Rate-limit handling token bucket algorithm
Rather than reacting only after a 429 response, implement a token bucket. Start with a capacity of 100 tokens and refill at 20 tokens per second. Every download consumes a token; when empty, pause briefly. This smooths traffic and avoids spikes that trigger throttling.
Chunked processing for billions of records
If your export runs into the billions, you’ll want a “map-reduce” style pipeline. Download each NDJSON chunk, push it into a Kafka topic, and let downstream consumers aggregate. That way you never hold more than a single file in memory and you can scale horizontally.
Error Handling and Retry Logic
Common HTTP error codes and meanings
- 400 Bad Request – malformed query parameters; fix the URL.
- 401 Unauthorized – token expired or missing scope; refresh the token.
- 403 Forbidden – the client lacks the required permissions; check the OAuth scopes.
- 429 Too Many Requests – hit the server’s rate limit; back-off and respect
Retry?After. - 500 Internal Server Error – transient issue; retry with exponential back-off.
Idempotent retries and back-off patterns
All $export calls are idempotent – you can safely repeat the same GET if you receive a 500. Store the original Content?Location so retries go to the same job. Use a jittered exponential back-off: delay = base * 2^attempt + random(0,1000 ms). This avoids the thundering-herd problem.
Testing, Validation, and Monitoring
Unit and integration tests for $export
Mock the FHIR server with wiremock or mockoon. Simulate a 202 response, then a 200 with a fake file list. Your test suite should assert that the client correctly stores the Content?Location and follows the polling loop.
Using FHIR validation tools
After you download a chunk, run it through the official validator.jar. Automate this step in your CI pipeline – a single malformed resource can break downstream analytics.
Monitoring export jobs with logs metrics
Emit structured logs (JSON) for each stage: start, poll, success, failure. Add Prometheus counters like bulk_export_requestsundefined and bulk_export_errorsundefined. Set alerts on error rate >?5?% or average job duration exceeding your SLA (usually 2 hours).
Real-World Use Cases and Best Practices
Population health analytics
A state health department used bulk export to pull all diabetes-related encounters from 150 clinics nightly after evaluating options with a complete guide to choosing the best Epic FHIR integration vendor. By streaming NDJSON directly into a Snowflake stage, they cut ETL time from 12 hours to under 30 minutes. The secret? Parallel downloads and a token-bucket limiter that kept the API under the 100 req/min quota.
Clinical research data pulls
During a multi-site trial, researchers needed a baseline cohort of 2 million patients. They launched a system-level export, stored the chunks in an Azure Data Lake, and then ran Spark jobs to filter on inclusion criteria. The whole process took 4 hours – a huge win over the manual CSV pulls they used before.
Migration to cloud data lakes
One hospital system migrated from an on-prem HAPI server to Google Cloud Storage; teams looking to undertake similar moves can follow a practical guide to FHIR R4 migration for healthcare teams. They scripted the $export flow, validated each NDJSON file, and used Dataflow to transform the resources into Parquet. The job ran nightly with zero human intervention, and the audit logs satisfied their compliance officer.
Wrapping Up
Implementing bulk FHIR data export isn’t rocket science, but it does demand a disciplined approach: verify server capabilities, handle OAuth correctly, respect async polling, and build resilient retry logic. The performance tricks – parallel downloads, token-bucket rate limiting, and chunked downstream processing – turn a simple export into a scalable pipeline that can handle billions of records.
Take these steps, test them in a sandbox, and then roll out to production with proper monitoring. You’ll unlock fast, standards-based data pipelines that power analytics, research, and migration projects without ever choking your FHIR server.
Frequently Asked Questions
How do I initiate a Bulk FHIR $export request on a server?
Send a GET request to the server’s /[base]/$export endpoint with required query parameters (e.g., _outputFormat, _since). Include the appropriate Authorization header. The server responds with a 202 Accepted and a Content-Location header pointing to the status URL.
What authentication methods are supported for Bulk Data Export?
Most FHIR servers require OAuth 2.0 bearer tokens, typically obtained via client credentials or authorization code flows. Some implementations also accept SMART on FHIR scopes like patient/*.read or system/*.read. Ensure the token includes the bulk-data export scope defined by the server.
How can I monitor the status of an asynchronous export job?
Poll the URL provided in the Content-Location header using GET requests. The response contains a status field (e.g., “in-progress”, “completed”, “failed”). Once the status is “completed”, the response includes a list of file URLs for download.
What format are the exported bulk data files and how are they stored?
Exported files are usually NDJSON (newline-delimited JSON) or CSV, as specified by the _outputFormat parameter. The server packages them in a ZIP archive or provides individual file URLs in a manifest. Files are hosted on a secure endpoint, often requiring the same bearer token for download.
What are common pitfalls and best practices when implementing Bulk FHIR export?
Avoid hard-coding endpoint URLs; use the server’s CapabilityStatement to discover the $export operation. Implement exponential backoff when polling status to reduce load. Validate file integrity after download and respect rate-limit headers to prevent throttling.